AI Lip Sync Looks Wrong? Fix the Input Before You Render Again
The mouth moves, but the video still looks wrong. Before buying more credits, take a 5–10-second section and check three things: whether the face is readable, whether the voice is isolated, and whether the mismatch is constant or grows over time. This guide combines YouTube tutorials reviewed on October 17, 2026, current provider documentation, and two earlier LipSyncX examples. It gives you a way to choose the next edit without rerendering the whole video.
Find the symptom before changing the model
Start with the downloaded file in your editor. If that file looks right but an uploaded copy does not, investigate the export or playback path first. A fresh AI render changes the picture; it does not diagnose a problem introduced later.
| What you see | Check first | Smallest useful next test |
|---|---|---|
| Lips stay ahead of or behind speech by a similar amount | Audio placement in the editing timeline | Adjust the track position on a duplicate timeline |
| Timing starts well and separates later | Clip durations and speed changes | Compare timestamps near the beginning and end |
| Timing seems right, but the mouth never quite closes | A clear word containing P, B or M | Inspect that word, then try cleaner speech with the same face |
| Face or teeth change when the head turns | Source angle, detail and obstructions | Use a clearer, less turned shot with the same audio |
| The wrong person talks | Speaker selection and overlapping voices | Test one face and one voice alone |
These are diagnostic suggestions, not proof of a cause. At 30 frames per second, one frame is about 33 milliseconds. That arithmetic can help you measure a shift; it is not a universal acceptable-sync threshold. Keep a copy of the original before changing timing.
Give the model a face it can actually read
Use a clear portrait or a medium close-up with the mouth visible. A hand, microphone or deep side angle can remove information the model needs. Upscaling the finished output cannot recover the original view of a hidden mouth.
In the Neural Frames masterclass, around 24:36, the presenter walks through a wide shot and advises leaving lip sync off it because the face occupies too few pixels. The useful production decision is to reserve visible singing for closer shots and let wider shots carry the scene. This is the platform's own tutorial, not an independent comparison.
Sync's media preparation guidance also cautions against full profiles and face obstructions. These recommendations describe that provider's inputs; they do not establish that every model has the same limits.
For a portrait workflow, start with the talking-photo tool. For footage you already filmed, use a video-input workflow rather than assuming a still-photo model will preserve the original performance.
Finish the voice track before rendering the face
Listen to the audio by itself. Check the product name, pauses and the final word of each sentence. For a diagnostic render, use one clear voice without background music or simultaneous speakers. Put the music back in the editing timeline after reviewing the speaking clip.
A Revovox walkthrough at 1:05–1:28 shows reviewing translated segments and correcting names before final dubbing. That is the transferable step here. Its subscription prices and language list are not a specification for LipSyncX.
For an original test line, try: “Please bring my blue folder. Five visitors will meet me before noon.” It gives you several lip closures and changes of mouth shape to inspect. Record it naturally; this is a suggested test, not a recording we generated for this article.
For translated footage, review meaning and pronunciation before video dubbing. If the spoken line changes after rendering, the face may need another pass too.
Compare the same input, not two impressive demos
The opening of Magic Hour's four-tool comparison uses the same 15-second video and audio for each tool. That is a useful comparison method. The channel sells one of the tools being compared, so treat its scores as a vendor assessment.
ElevenLabs' official tutorial at 0:46–1:38 places three model outputs side by side and discusses differences in expression and movement. It illustrates why a sharper output and a more restrained performance are separate choices. The tutorial's model menu and limits belong to that demonstration, not today's LipSyncX catalog.
Here are two existing LipSyncX outputs you can inspect yourself:
LipSyncX Fast: the original eight-second lesson introduction
LipSyncX Pro: the same portrait and recording
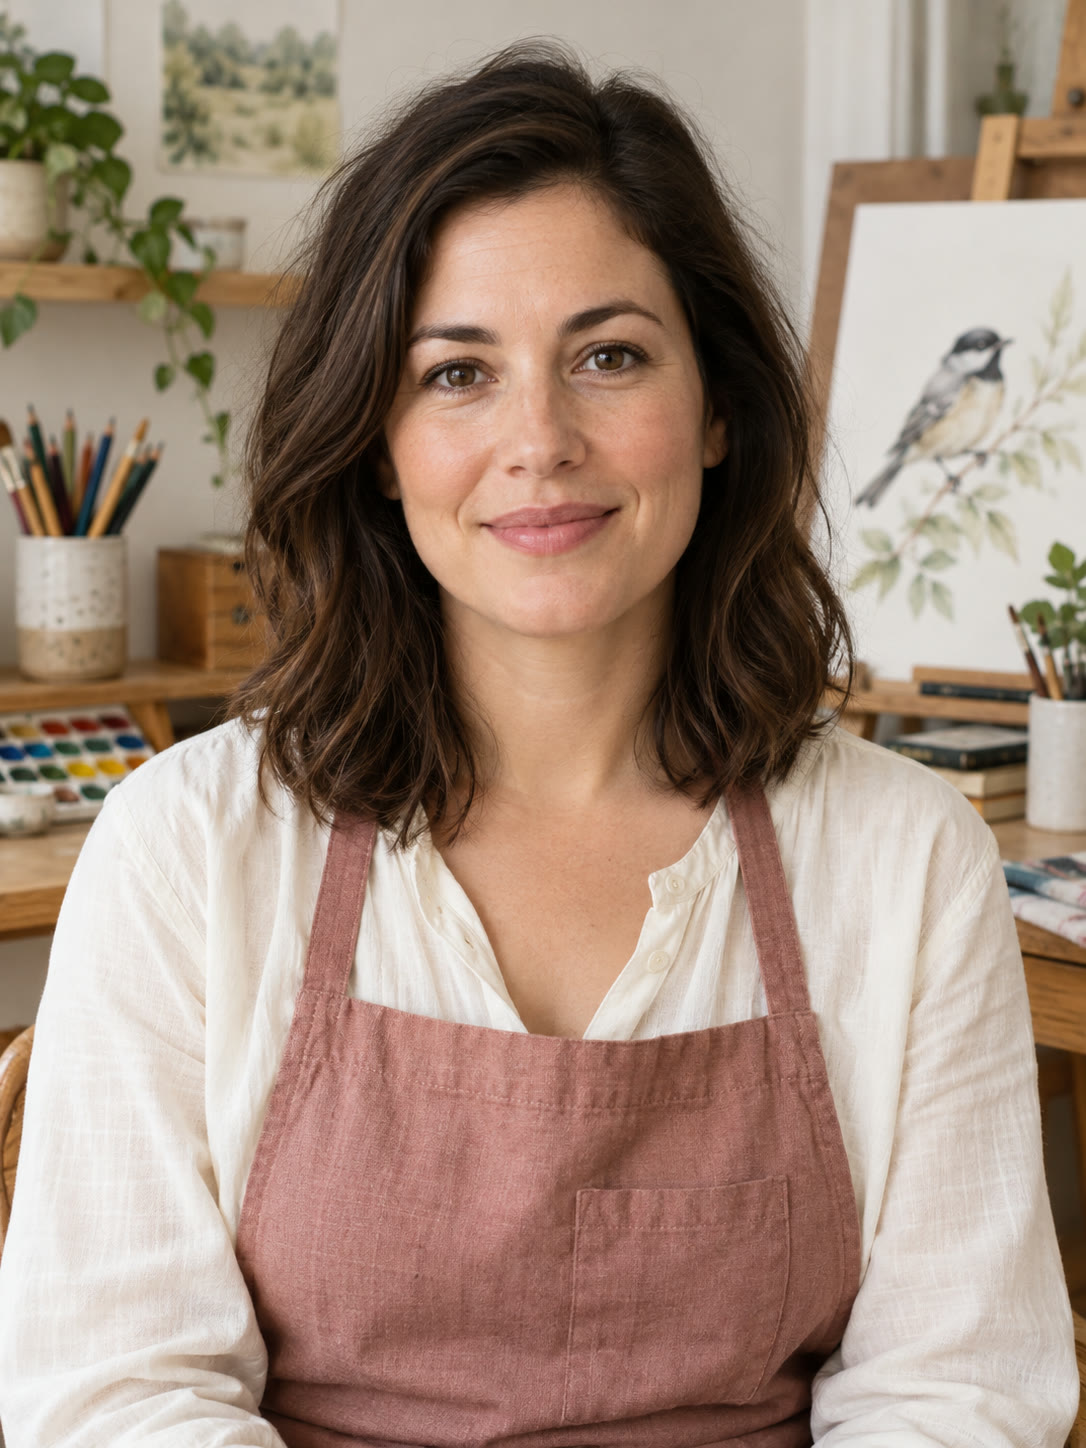
Both clips were generated by our team on October 14 with a fictional presenter and synthesized speech. Each used 480p and cost 20 credits. They are existing examples, not a new benchmark of the fixes in this guide. The original example notes document the inputs and charges.
Use this review sheet when comparing your own outputs. Keep duration, audio and source fixed; change one setting at a time.
| Review pass | What to write down |
|---|---|
| Normal playback | Would you publish it at the intended display size? |
| Target words | Timestamp where closure or timing becomes distracting |
| Face consistency | Changes to teeth, jaw, beard or facial outline |
| Performance | Whether expression fits the line; unwanted head or camera movement |
| Cost | Quoted credits, number of attempts, number of usable clips |
Watch at normal speed first. Half-speed playback helps locate an issue, but a slowed clip is not how most people will see your finished work.
Set a retry budget before the next render
Choose a short section containing the problem and decide what each attempt will test. For example: a clearer source image, a cleaned voice track, then a different available model. Stop after your chosen budget and compare the files. Changing all three together makes it harder to learn what helped.
As checked on October 17, the smallest listed LipSyncX pack provides 60 credits for $2.99 in USD. With the earlier 20-credit examples, that balance covers three such attempts, not three guaranteed publishable videos. Actual quotes depend on the current model, resolution and duration.
Track credits per usable clip alongside price per render. A hypothetical pair of 20-credit attempts producing one keeper costs 40 credits per usable clip. That is arithmetic, not a measured success rate.
FAQ
Can I fix everything by moving the audio track?
A track shift can address a constant offset introduced in editing. It cannot redraw an incorrect mouth shape or resolve timing that changes throughout a clip. Compare the beginning and end before choosing that fix.
Should every shot in a music video have lip sync?
No. Use performance shots where the mouth is readable, then cut to other footage while the soundtrack continues. The Neural Frames tutorial demonstrates this shot-selection approach; it does not require every shot to show a singer.
Does a successful render mean the result is publishable?
No. A completed job still needs visual and audio review. LipSyncX's pricing policy describes returning charged credits for provider-side failed renders; that is different from guaranteeing satisfaction with every completed output or issuing a cash refund.
Make the next attempt answer one question
Choose one portrait, one short recording and one symptom from the first table. Open the LipSyncX talking-photo tool, check the quote and generate that section. Keep the downloaded file and your review notes before trying another variation.